
Run End-to-End Tests from Your Terminal with Kane CLI
Author and Run Tests Right from the Terminal in Natural Language, with an Evidence-Backed Pass or Fail from a Real Browser.
npm install -g @testmuai/kane-cli
- TestMu AI (Formerly LambdaTest)
- /
- Blog
- /
- AI Coding Agents in 2026: 120+ Tools Mapped, and the Verification Layer They All Need
AI Coding Agents in 2026: 120+ Tools Mapped, and the Verification Layer They All Need
Every AI coding agent, IDE, app builder and model of 2026 mapped in one place, plus the verification layer they all skip: Kane CLI and Agent Assurance.
Last Updated on:
AI coding agents are AI tools that take a software task in plain language and complete it on their own. They read your codebase, plan the change, edit files, run commands and tests, and fix what fails, without your approval at each step.
The leading agents in 2026 are Claude Code, OpenAI Codex, Cursor, GitHub Copilot's cloud agent, Gemini CLI, Devin, and open-source options such as OpenCode, Cline, and Aider. The top Terminal-Bench 4.0 score, 64.8% for Claude Code with Opus 5.5, still leaves about a third of hard tasks unsolved. This guide compares the agents, then shows how to make any of them prove its work with a testing agent such as Kane CLI before you merge.
TL;DR
AI coding agents are tools that write, edit and ship code from a prompt, and more than 120 of them exist in 2026, from terminal agents to AI IDEs, cloud agents and app builders. They solve generation, but none independently proves the software works, so teams pair them with a separate verification layer.
- Best overall for hard, repo-wide work: Claude Code. Claude Code with Opus 5.5 holds the top Terminal-Bench 4.0 agent score at 64.8%, and it follows CLAUDE.md project rules. Open source: No.
- Best for background tasks: OpenAI Codex. Codex with GPT-6.1 Sol scores 58.2% on Terminal-Bench 4.0 and takes delegated work in a cloud sandbox. Open source: CLI only.
- Best inside an editor: Cursor. Cursor's agent plans and edits across files while you watch, and you choose the model. Open source: No.
- Best open source coding agent: OpenCode. OpenCode runs in the terminal, as a desktop app, or in the IDE, and works with any model. Open source: Yes.
Whichever you pick, test what it builds. Kane CLI from TestMu AI runs user flows in a real Chrome browser, and Agent Assurance, delivered by Rook, tests the AI agents you ship.
What Is a Coding Agent?
A coding agent is an AI system that writes and changes software by running a loop: it reads the task and the code, plans, edits files, runs commands, reads the results, and repeats until the goal is met or it gets stuck. The large language model decides the next step; the agent's tools (file editing, a shell, search, a browser) carry it out. Because it runs that loop without asking for approval at each step, a coding agent is also called an autonomous coding agent or an AI agent for coding.
When the loop includes a browser through Playwright, Playwright sandbox for AI agents covers which build it launches and whether its sandbox is on.
This short shows where Claude Code, Codex, Cursor and Copilot each fit.
How one coding agent task runs:
- Read the goal and gather context. The agent searches the repo, opens relevant files, and reads instruction files such as
AGENTS.mdorCLAUDE.md. - Plan. It breaks the task into steps and decides which files to change.
- Act. It edits code and runs shell commands: install, build, lint, test.
- Observe. It reads compiler errors, test output, and logs.
- Repeat or finish. It fixes what failed and loops until its checks pass, then summarises the change or opens a pull request.
The weak point is step 4. An agent can only fix what it can observe. If its only signal is "the build passed, and unit tests are green", it has no way to see that the checkout button now sits under the cookie banner.
Coding Agent vs AI Coding Assistant
| AI coding assistant | AI coding agent | |
|---|---|---|
| Unit of work | A line, a function, a chat answer | A whole task: a feature, a bug fix, a refactor |
| Who drives | You accept or reject each suggestion | The agent runs many steps on its own |
| Tools | Your editor | Editor, shell, file system, search, sometimes a browser |
| Output | Suggested code | Edited files, a passing build, often a pull request |
| Examples | Inline autocomplete, chat in the IDE | Claude Code, Codex, Cursor agent mode, Copilot cloud agent, Devin |
Most tools now do both. Cursor and GitHub Copilot started as assistants and added agent modes; Claude Code and Codex were agents from the start. Coding agents are one category among many, and a broader set of AI agent examples places Claude Code and GitHub Copilot beside research, customer service and industry agents.
Types of AI Coding Agents
| Type | Where it runs | Examples | Best when |
|---|---|---|---|
| IDE agents | Inside your editor | Cursor, GitHub Copilot agent mode, Devin Desktop (formerly Windsurf), Cline, Kilo | You want to watch and steer every change |
| Terminal (CLI) agents | Your shell | Claude Code, Codex CLI, Gemini CLI, OpenCode, Aider | You work in the terminal or want agents in scripts and CI |
| Cloud / background agents | A remote sandbox | Codex cloud, GitHub Copilot cloud agent, Devin, Cursor cloud agents | You want to hand off tasks and get a pull request back |
| App builders | A browser | Lovable, Bolt, v0, Replit | Non-engineers building a prototype or small app |
For a deeper look at the terminal category, see our comparison of agentic coding CLI tools.
The 2026 AI Coding Landscape: 120+ Tools in Seven Categories
This AI coding tools list splits the 2026 market into seven categories, and each one leaves a different verification gap. Find your tools in the table, then read across to what still needs proving before release.
| Category | Tools | What it produces | What still needs verifying | TestMu AI layer |
|---|---|---|---|---|
| Terminal and CLI coding agents | Claude Code, Codex, Gemini CLI, Copilot CLI, Cursor CLI, Amp, Droid, OpenCode, Grok Build, Muse Code, Kimi Code, Qwen Code, Mistral Vibe, Goose, Crush, Aider, Warp, Codebuff, ForgeCode, Command Code, Letta Code, Deep Agents CLI, Plandex, mini-swe-agent, Hermes Agent | Multi-file diffs and PRs from a terminal prompt | Real user flows across web, API and mobile, not just the unit tests the agent wrote | Kane CLI, called from the same terminal |
| AI IDEs and editor assistants | Cursor, GitHub Copilot, Antigravity, Kiro, Zed, Trae, Qoder, CodeBuddy, ZCode, Junie, JetBrains AI, Augment Code, Cline, Kilo Code, Tabnine, Qodo, Zencoder, Verdent, Tabby, Sweep, Comate, CodeGeeX, Blackbox AI, Bito, avante.nvim, CodeCompanion | In-editor edits, completions and agent-mode changes | Regressions in flows the developer did not open in the editor | Kane CLI from the IDE terminal; KaneAI for PM and manual-test sign-off |
| Cloud and async autonomous agents | Devin, Jules, Copilot cloud agent, OpenHands, Cosine, Tembo, Ona, Roomote, Manus, OpenClaw | PRs opened with no human at the keyboard | Evidence a reviewer can trust without rerunning the work | Kane CLI in CI with an evidence file and PR comment; HyperExecute for scale |
| Vibe-coding and AI app builders | Lovable, v0, Bolt, Replit, Base44, Emergent, Rork, Anything, Google AI Studio, Canva Code, Macaly, a0.dev, CatDoes, Vibecode, Dyad, Chef, Tempo, Rocket, Blink, Readdy, Floot, Atoms, Pythagora, HeyBoss, YouWare, Miaoda, Hostinger Horizons | Whole apps from a prompt, often by non-engineers | Checkout, auth and data flows on real browsers and devices before customers hit them | Kane CLI or KaneAI in plain English; Real Device Cloud |
| Design-to-code and low-code | Stitch, Figma Make, Builder.io, Kombai, Anima, Locofy, Magic Patterns, Onlook, Subframe, FlutterFlow, Draftbit, Superblocks | Front-end code and screens from designs | Visual fidelity, responsiveness and accessibility across 3,000+ browser and OS combinations | SmartUI visual testing, Accessibility Testing, cross-browser cloud |
| Platform-native and spec-driven agents | Netlify Agent Runners, Agentforce Vibes, IBM Bob, GitLab Duo, Rovo Dev, Tessl | Changes inside a platform such as Salesforce, GitLab, Atlassian or Netlify | That the deployed change still works in the packaged app and its integrations | Kane CLI and KaneAI for Salesforce and enterprise-app flows; TestMu AI's test management platform |
| Models and AI assistants | ChatGPT, Claude (Opus, Sonnet, Haiku), Gemini, Grok, DeepSeek, Kimi, Qwen, Vibe (formerly Le Chat), Codestral, Devstral, Llama, GLM, MiniMax, KAT-Coder, gpt-oss, Doubao, Microsoft Copilot, Perplexity | The intelligence behind every tool above, and the brains of the agents you ship | How agents built on these models behave: tool calls, prompt injection, instruction override | Agent Assurance with Rook for agents that act; Agent Testing for chat and voice |
The generators in these seven rows change every quarter, but the verification layer stays. Teams that swap Cursor for Claude Code, or Lovable for Replit, keep the same Kane CLI tests and the same evidence trail. For teams still choosing between those two app builders, our Lovable vs Replit comparison covers features, pricing and deployment.
For the app-builder row in more depth, see our guides to vibe coding tools and vibe coding verification with Kane CLI. To choose between an app builder and an AI code editor, see Replit vs Cursor and Lovable vs Cursor. The Lovable vs Bolt comparison weighs two app builders on stack, pricing and native mobile apps. For a ranked view of hosted tools, see the best AI app builders.
What Is Agentic Coding?
Agentic coding is the practice of delegating entire tasks to coding agents rather than writing every line yourself. You write the goal, the constraints, and the definition of done; the agent does the implementation loop; you review the result. It works best when "done" is something the agent can check by running a command, which is why test setup decides how far agentic coding scales on your team.
The Best Coding Agent in 2026: AI Coding Agents Compared
There is no single winner among the best AI coding agents in 2026; the right one depends on where you work and how much you want to hand off. Benchmark figures below come from the Terminal-Bench 4.0 leaderboard as of November 2, 2026; "model-set" means the score depends on the model you choose.
| Agent | Type | Best for | Open source | Terminal-Bench 4.0 |
|---|---|---|---|---|
| Claude Code (Anthropic) | Terminal, IDE, cloud | Hard, repo-wide changes and long tasks | No | 64.8% (Opus 5.5) |
| OpenAI Codex | Terminal, IDE, cloud | Background tasks returned as PRs | CLI: yes | 58.2% (GPT-6.1 Sol) |
| Cursor | IDE, CLI, cloud agents | Fast, steerable edits inside the editor | No | Model-set |
| GitHub Copilot cloud agent | IDE + GitHub cloud | Issue-to-PR work for teams already on GitHub | No | Not listed |
| Gemini CLI (Google) | Terminal | Open-source CLI for Google Cloud stacks | Yes | No agent entry |
| Devin (Cognition) | Cloud | Hands-off delegation of well-scoped tickets | No | Not listed |
| OpenCode | Terminal, desktop, IDE | Any model, self-hosted or BYOK | Yes | Model-set |
| Cline / Kilo | IDE extension, CLI | Open-source coding agent in VS Code or JetBrains with your own keys | Yes | Model-set |
| Aider | Terminal | Small, git-native changes with clear commits | Yes | Model-set |
- Claude Code - the strongest agent on hard benchmarks today. It reads large repos well, follows
CLAUDE.mdproject rules, and supports skills and hooks, so you can teach it your test commands once. Pick it when correctness on complex changes matters most, and use Claude Code app testing to check what it builds. - OpenAI Codex - close behind on capability, with GPT-6.1 Sol scoring 58.2% on the same benchmark. Strong for delegating background work in a cloud sandbox and reviewing the resulting pull request. Its CLI reads
AGENTS.md. - Cursor - the best experience if you live in the editor: agent mode plans and edits across files while you watch, and cloud agents take longer tasks. You choose the model, so quality tracks the model you pick.
- GitHub Copilot cloud agent - assign an issue and get a pull request, with the work running in GitHub's environment. The natural choice when your reviews, CI, and permissions already live in GitHub.
- Gemini CLI - Google's open-source terminal agent, and it works well inside Google Cloud projects. Unpaid-tier and Google One users were moved to Antigravity CLI on June 18, 2026, and the Gemini CLI README points to Antigravity CLI for the latest Gemini models.
- Devin - the most autonomous option: you hand it a ticket, and it works in its own environment until it opens a PR. It does best with well-scoped tasks and clear acceptance criteria. The Devin review covers its plans, its self-testing, and how its public PRs ended.
- OpenCode, Cline, Kilo, and Aider - the open-source route. Bring your own model and keys, run locally or self-hosted, and keep full control of data. Quality depends on the model you connect, and an open-weight model such as DeepSeek V4.1 Flash can run either through its vendor's API or on your own hardware.
For terminal agents in more depth, see our agentic coding CLI tools comparison; for a head-to-head, see Claude Code vs Cursor.
How to Choose a Coding Agent
- Where do you work? Editor: Cursor or Copilot. Terminal: Claude Code, Codex CLI, or Gemini CLI. Want PRs while you sleep: Codex cloud, Copilot cloud agent, or Devin.
- How hard are the tasks? Large refactors and unfamiliar repos favor the top benchmark agents (Claude Code, Codex).
- Can your code leave your network? If not, use an open-source agent with a self-hosted model.
- Can the agent prove its work? The agent is only as reliable as the checks it can run. Before you compare agents, make sure each one can run your unit tests and an end-to-end check of the real app. The next section shows how.

Note: Give your coding agent a check it cannot grade itself. Kane CLI runs the user flow in a real browser and returns a pass or fail. Start free with TestMu AI.
Why Do AI Coding Agents Ship Broken Features?
AI coding agents ship broken features because they verify their own work using only the signals they can see (the compiler, the linter, and unit tests), and none of those run the app the way a user does. A coding agent can make every unit test pass, even when the login form no longer submits on mobile, a modal covers the pay button, or an API change breaks the page that calls it.
For a quick visual walkthrough of this concept, watch the video below from TestMu AI.
Subscribe to the TestMu AI YouTube channel for more tutorials on testing and automation.
Three gaps cause most of it:
- No eyes on the running app. Most agents never open the feature in a browser or on a device.
- Self-grading. The same agent writes the code, writes the tests, and declares success. If it misunderstood the requirement, its tests encode the same misunderstanding.
- No evidence for the reviewer. You get a summary that says "done", not proof of what the agent actually checked. A log the agent can edit is no proof either, which is the lesson of the OpenAI Hugging Face incident.
| Check | What it proves | What it misses |
|---|---|---|
| Type check and lint | Code is well-formed | Behaviour |
| Unit tests (often agent-written) | Functions return what the tests expect | Whether the tests match the requirement; the UI; integration |
| CI build | It builds in a clean environment | Whether a user can complete the flow |
| End-to-end run of the real app | A user can complete the flow in a real browser or on a device | This is the missing check |
The Coding-Agent Boom: A QA Problem for AI-First Mid-Market Teams
AI coding agents moved the bottleneck from writing code to trusting it. A team of 80 engineers running Claude Code, Cursor and Copilot CLI can now open more pull requests in a week than its reviewers and test suites were built to absorb.
In AI-first mid-market companies, these break first:
- Review capacity - Humans cannot read every agent-written diff, so green unit tests become the de facto approval. Unit tests written by the same agent that wrote the code share its blind spots.
- End-to-end coverage - Agents change UI flows, APIs and mobile screens faster than Selenium or Playwright scripts can be updated, so suites go stale or flaky.
- The agents you ship - Many mid-market teams now ship their own AI agents (support bots, internal copilots, MCP-connected workflows). An agent that reports "task done" is not proof the task was done.
Enterprises answer this with large QA departments. SMBs often accept the risk. Mid-market teams have neither the headcount nor the risk appetite, which is why they need an independent verification layer.
The principle: generation and verification should come from different systems. A coding agent writes the change; a separate testing agent runs the software the way a user would and returns evidence, which is how you verify AI-written code before it merges. Deciding what the testing agent checks, and reading the evidence it returns, is everyday work for an agentic quality engineer.
How to Make a Coding Agent Prove Its Work With Kane CLI
Kane CLI handles testing AI-generated code from the terminal: coding agents call it as one step in their loop, and TestMu AI describes it as a testing agent for you and a co-agent for your coding agent. It is not a coding agent and does not write your feature. You (or your coding agent) describe a user flow in plain English; Kane CLI drives a real Chrome browser (or an iOS Simulator or Android Emulator for native apps) and returns a pass or fail that the coding agent can read and act on.
That closes the loop at step 4 of the agent loop:
- The coding agent implements the change.
- It calls
kane-cli run "<what a user should be able to do>" --agent. - Kane CLI runs the flow on the real app and streams structured NDJSON, ending with a
run_endevent and an exit code: 0 passed, 1 failed, 2 setup or auth error, 3 timeout. - On failure, the agent reads the failing step and screenshot, fixes the code, and runs the same command again.
- Every run seals a
.evidencepack (steps, screenshots, DOM snapshots, console and network logs) that a human reviewer can replay.
What this looks like in practice. In TestMu AI's own walkthrough, Gemini CLI, working on a checkout page, ran kane-cli run "go to http://localhost:3000, click 'Buy Pro', assert the total due today shows '$19.00'" --agent. The run failed. Gemini CLI read the result, fixed the price mismatch on the page, and re-ran the identical command, which passed.
In the same walkthrough, Claude Code's first end-to-end run failed at step 9 of 9; after the fix, the saved test replayed as passed.
What Kane CLI does that a coding agent's own tests do not:
- Replayable evidence - the
.evidencefile also holds the verdict, runs upload to TestMu AI Test Manager by default, and the GitHub Action can post the result as a pull request comment. - Healing that never fakes a pass - step-heal re-finds an element that moved or changed markup, and flow-heal re-reasons the path only when a step can't be healed, never the acceptance criteria. A wrong result is reported as a bug and is never healed into a pass.
- Five surfaces - web on real Chrome, API requests and responses, the Android Emulator, the iOS Simulator, and real Android and iOS devices for suites sent to the TestMu AI grid.
- No lock-in - any recorded flow exports as Playwright code, so teams already on Playwright can keep it. If your coding agent drives a browser through Playwright MCP today, Kane CLI vs Playwright MCP shows how the two tools differ.
Proof points (vendor-reported, from the Kane CLI page):
- Ranked first for browser testing in TestMu AI's Kane CLI PRISM benchmark (2026-Q4), with a 76.7% overall score across 7 tools.
- Kept 16 of 16 live-site tests passing over 11 rounds, against 2 of 16 for a Playwright baseline.
Why it works with any coding agent. TestMu AI names Claude Code, Cursor, Codex, Gemini CLI, VS Code and GitHub Actions as integrations. Kane CLI is a command, not an IDE plugin, so any agent with a shell can call it. A ready-made skill makes it a testing agent for Claude Code, Codex CLI, and Gemini CLI, and a hosted instruction file lets other agents such as Cursor use it (agents.md). Runs can be saved as _test.md files, committed with the code, and re-run in GitHub Actions, GitLab CI, or Jenkins.
Limits to know. The CLI is free to install, and runs use KaneAI credits from your TestMu AI account, whether they run on your machine or on the TestMu AI cloud grid. Local Android Emulator and iOS Simulator runs need an Apple Silicon Mac, while kane-cli testrun run --remote sends mobile suites to the grid from any machine (Kane CLI remote execution). Kane CLI checks behavior from the user's side; you still need unit tests, code review, and security scanning.
Set Up Kane CLI With Your Coding Agent in 5 Minutes
1. Install the skill for Claude Code, Codex CLI, or Gemini CLI:
npx @testmuai/kane-cli-skill2. Install Kane CLI (if the skill didn't already):
npm install -g @testmuai/kane-cli3. Log in with your free TestMu AI account, without opening a browser:
kane-cli login --username "<your-username>" --access-key "<your-access-key>"
kane-cli whoami
4. Tell your agent what "done" means. Add one line to AGENTS.md or CLAUDE.md:
Before you say a UI task is done, run `kane-cli run "<the user flow you changed>" --agent --headless`
against http://localhost:3000 and fix the code until it exits 0.
5. Run it in CI. Save a passing run as a test with --name, commit the _test.md file, and run it on every pull request with --headless --timeout 240.
For Cursor, point the agent at https://www.testmuai.com/kane-cli/agents.md. Beyond the one-line rule, the guide on how to add testing to AI coding tools shows the hook that keeps each agent working until its tests pass.
The Workflow: From Agent-Written Code to Verified Release
The workflow every AI-first team can run today has one rule: the agent that writes the change never approves it.
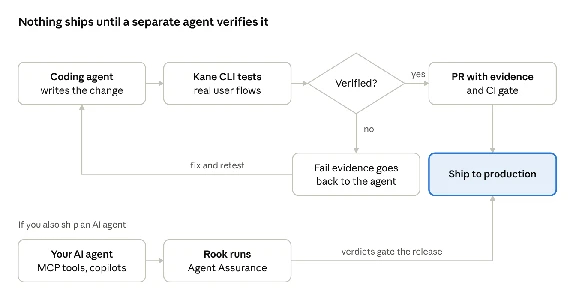
A coding agent from any row of the landscape table writes the change; Kane CLI runs the real flows and either sends fail evidence back to the agent or passes, so the PR opens with proof attached. If the release includes an AI agent, Rook's Agent Assurance verdicts gate it too.
# inside Claude Code, Cursor, Codex or any agent that can run a shell command
kane-cli run "<the user flow you changed>" --agent   # structured NDJSON the coding agent reads; exit 0 = pass, 1 = fail
Agent Assurance and Rook: Testing the AI Agents You Ship
Agent Assurance is testing for AI agents that act (they call tools, write files, hit APIs and open pull requests), and it grades what an agent actually changed, not what it says it did. Rook is the command-line tool that delivers Agent Assurance. It is self-serve: install it from npm and start a 14-day free trial.
npm install -g @testmuai/rook@latestKane CLI covers the software your coding agents build for humans. Agent Assurance covers the agents you ship that take actions, such as MCP-connected workflows, internal copilots that call tools, and automation agents running on Claude, GPT, Gemini, Qwen or DeepSeek models.
How Rook works, in four phases:
- Discover - Rook reads your repository, PRD or policy docs and connects to MCP servers to see which tools exist. Undeclared fields are marked unknown, not guessed.
- Generate - Rook derives functional and adversarial scenarios, each with its own gradable criteria. There are no tests to write.
- Run and judge - Rook invokes the agent and checks each criterion against files, artifacts and tool calls.
- Report - Every criterion gets pass, fail or unable to verify. Unverifiable results are reported separately and kept out of the pass rate; TestMu AI calls the unverified share the assurance gap.
Adversarial by default. Prompt injection, instruction override and tool misuse are a first-class scenario family, generated by default rather than added on.
Where it runs. The Rook skill can be driven from Claude Code, OpenAI Codex CLI and Gemini CLI (with more listed in the docs), and Rook gates releases in GitHub Actions, Jenkins and Argo CD.
| Category | Who works with what | TestMu AI product |
|---|---|---|
| Humans and software | People use web and mobile apps | KaneAI, Kane CLI |
| Humans and agents | People talk to chat, voice, phone and IVR agents | Agent Testing |
| Agents and the systems they act on | Agents call tools, MCP servers and APIs, write files and open pull requests | Agent Assurance, delivered by Rook |

Next Steps: Pick an Agent, Then Add a Check
Choose the agent that fits where you work, then make one end-to-end check part of its definition of done. The Kane CLI with AI coding agents docs walk through the full setup for each agent.
Testing from the terminal? Kane CLI by TestMu AI lets SDETs and developers plan, write, run and debug tests from the command line.
Author
Shantanu Wali
Blogs: 13

Shantanu Wali is Vice President of Product Management at TestMu AI, where he owns several product lines across the testing platform, including the Real Device Cloud and the Digital Experience Testing Cloud. He has also contributed significantly to the development and scaling of KaneAI, TestMu AI's flagship GenAI-native testing agent that uses natural language to make software testing faster and more reliable in this AI era. He brings 7+ years of experience across software development and product management, starting as a backend developer at Infosys building solutions for Fortune 500 clients. Shantanu holds an MBA from IIM Calcutta and a B.Tech in Mechanical Engineering.
Reviewer

Mayank Bhola
Reviewer
Mayank Bhola is Co-Founder and Head of Products at TestMu AI, where he leads the entire product portfolio across KaneAI, Kane CLI, HyperExecute, SmartUI, the Real Device Cloud, Accessibility, and other software testing product lines. As an early Lead Architect he designed and built the company's flagship Tunnel technology from scratch, created the React-based automation platform, and architected the data-intensive pipelines and FAAS services that scale it. He brings more than 10 years of experience in software development and product engineering, with earlier roles as Head of Technology at Juggernaut Books and Senior Software Engineer at PressPlay TV and Zomato. Mayank holds a B.Tech in Computer Engineering from JIIT Noida.


AI Coding Agents FAQs
Did you find this page helpful?
More Related Blogs

TestMu AI forEnterprise
Get access to solutions built on Enterprise
grade security, privacy, & compliance
- Advanced access controls
- Advanced data retention rules
- Advanced Local Testing
- Premium Support options
- Early access to beta features
- Private Slack Channel
- Unlimited Manual Accessibility DevTools Tests